Research
Notes from the lab
What we are building, what we are measuring, and what surprised us.
Looking for earlier material? Browse the legacy archive.
 7 min read
What Quantization Actually Costs You
Quantization stores a model's weights in fewer bits, so it fits in less memory and often runs faster. Where the quality goes, and how to measure it.
Language ModelsRead 7 min read
Securing an AI Application Starts With What It Can Reach
You cannot make a language model refuse every attack. You can limit what it can read, change and send. A practical threat model for AI applications.
AI securityRead 8 min read
What Agentic AI Actually Means, and What It Doesn't
Agentic AI is a model that chooses its own next step, not a chatbot with a new label. A working definition, where agents pay off and where they fail.
Agent ArchitecturesRead 6 min read
You May Not Need a Vector Database
Most retrieval systems start with a dedicated vector database they do not yet need. What exact search, pgvector and approximate indexes actually trade.
RetrievalRead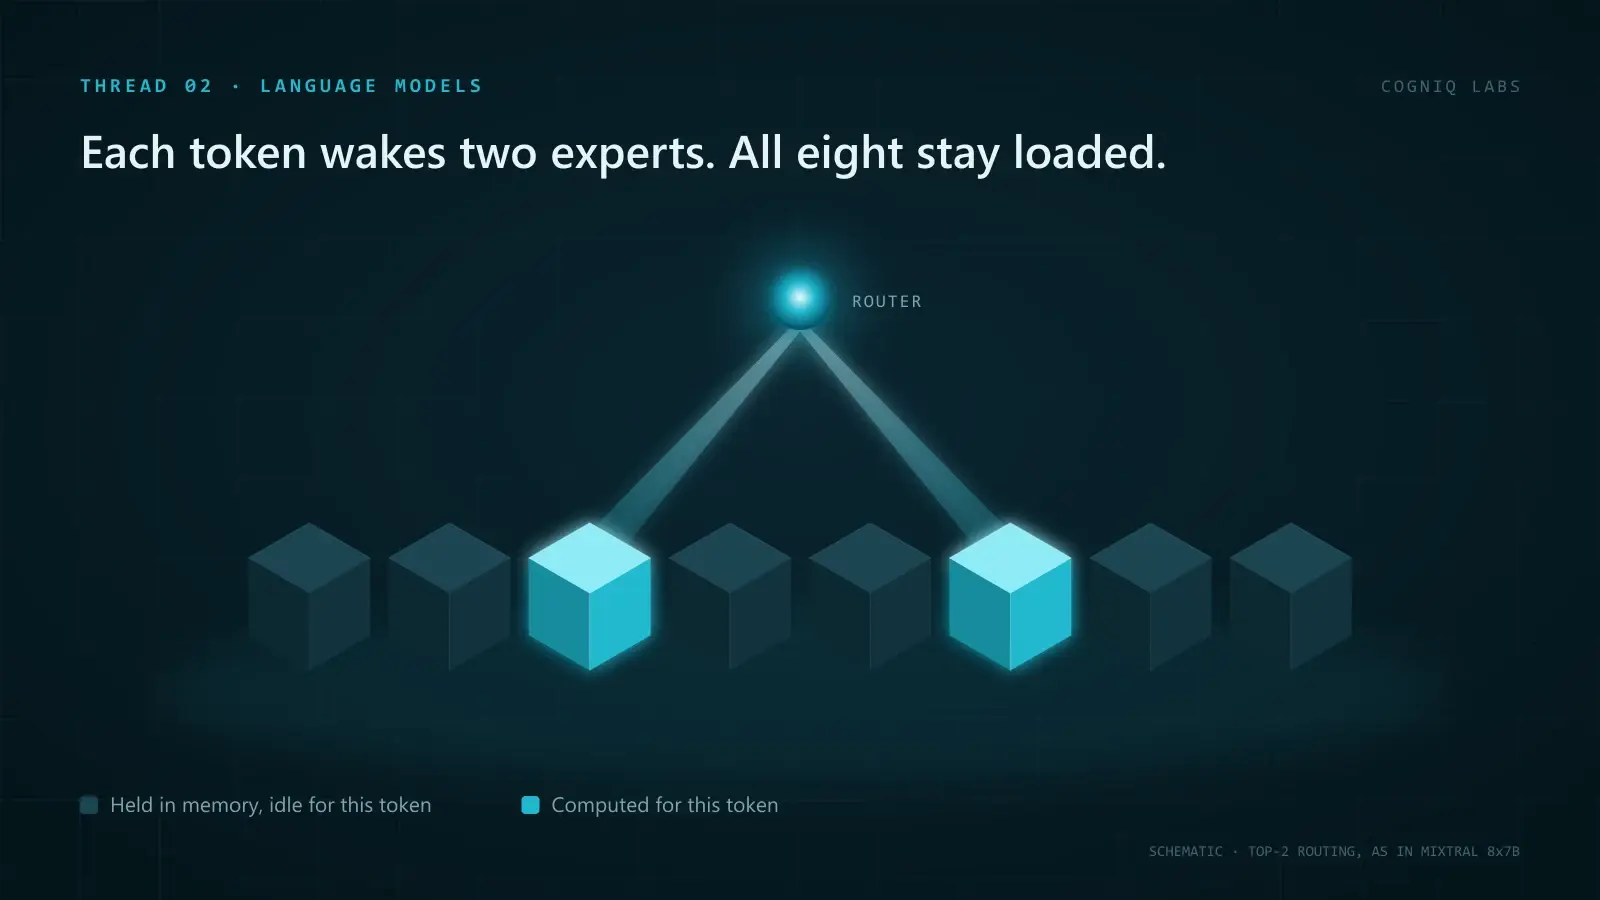 6 min read
Mixture of Experts: Cheaper per Token, Not per GPU
A mixture-of-experts model runs only a few experts per token, so compute falls. Every expert still has to sit in memory. Where that trade pays off.
Language ModelsRead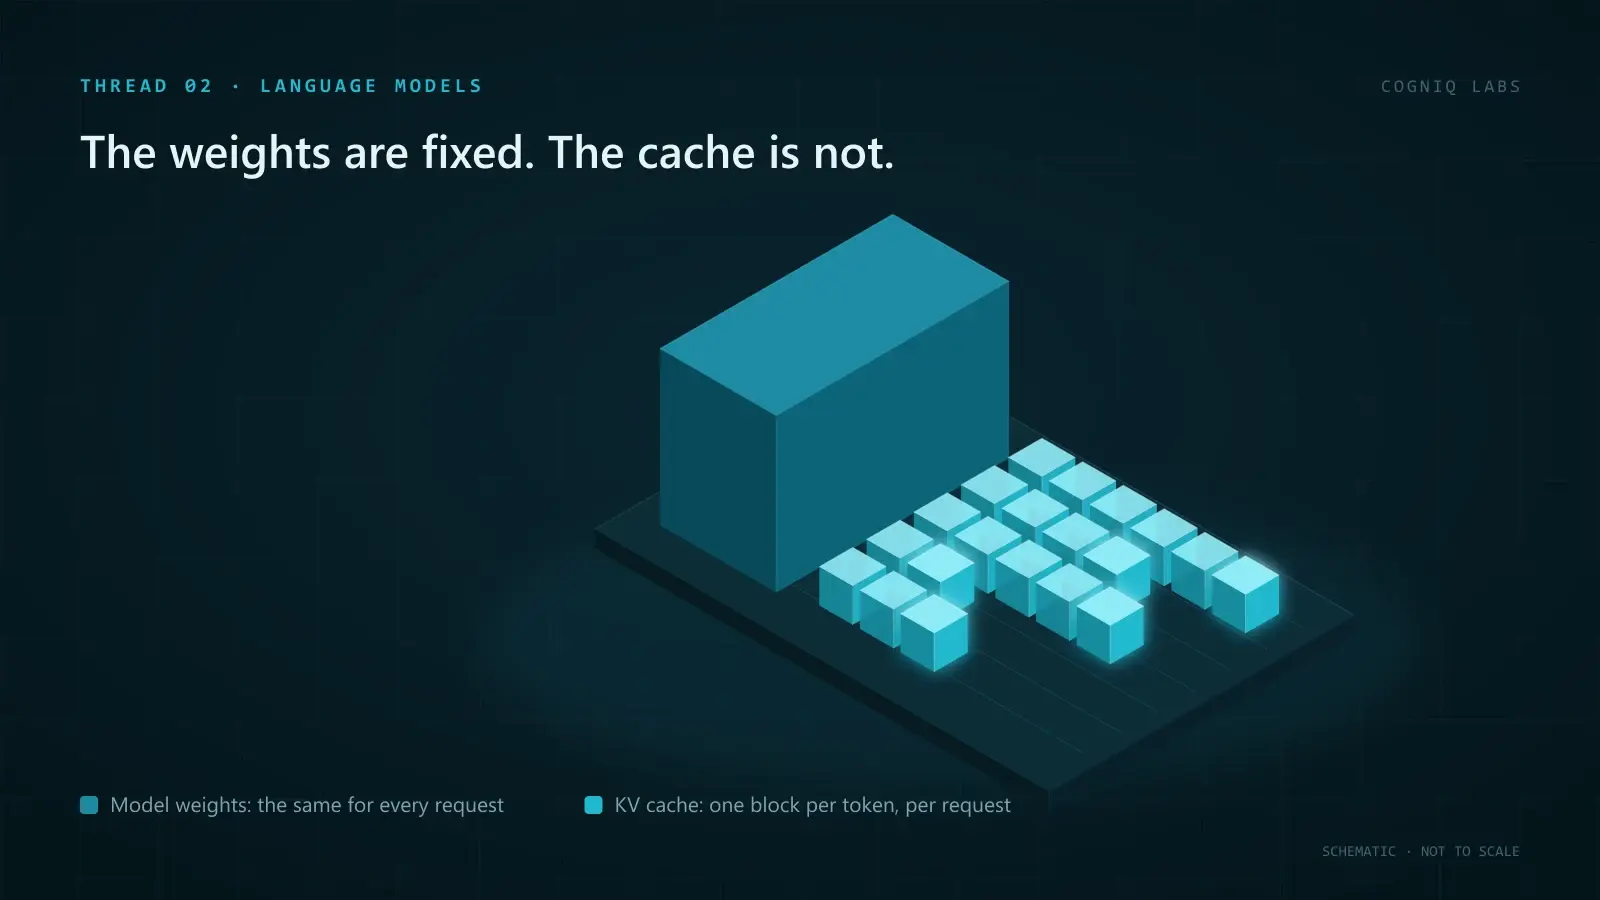 6 min read
What the KV Cache Actually Costs You
The KV cache makes generation fast and quietly decides how many requests a GPU can serve. Why it grows with every token, and what shrinks it.
Language ModelsRead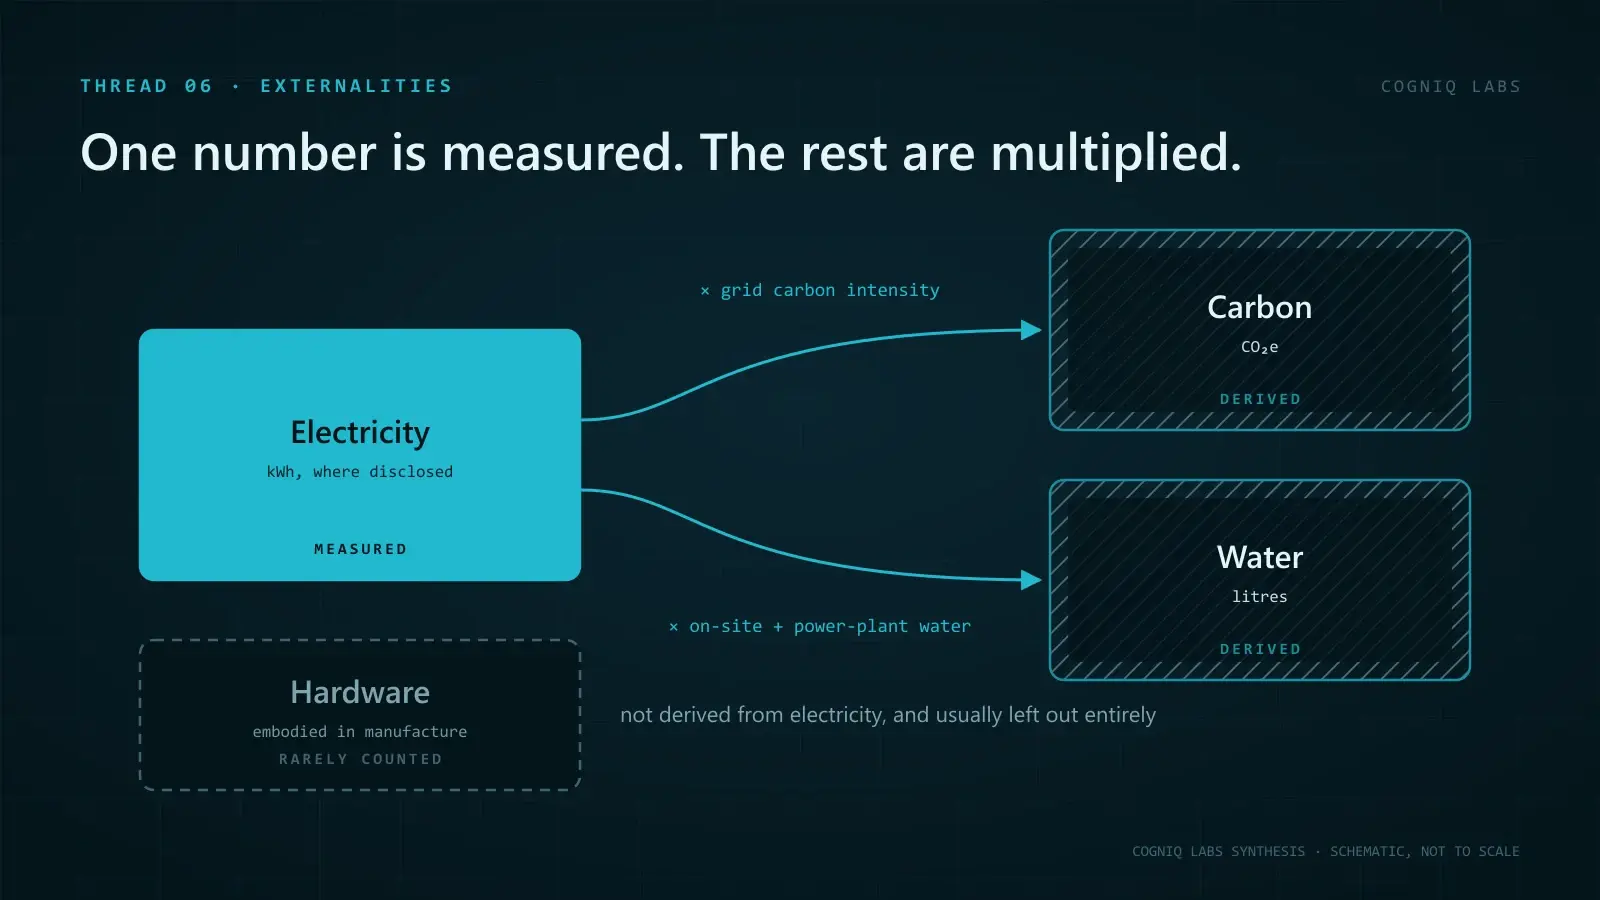 4 min read
Is AI Bad for the Environment? Start With What's Measured
Most figures on AI's environmental cost are multiplied from one measured number, electricity. Where the others come from, and what gets left out.
ExternalitiesRead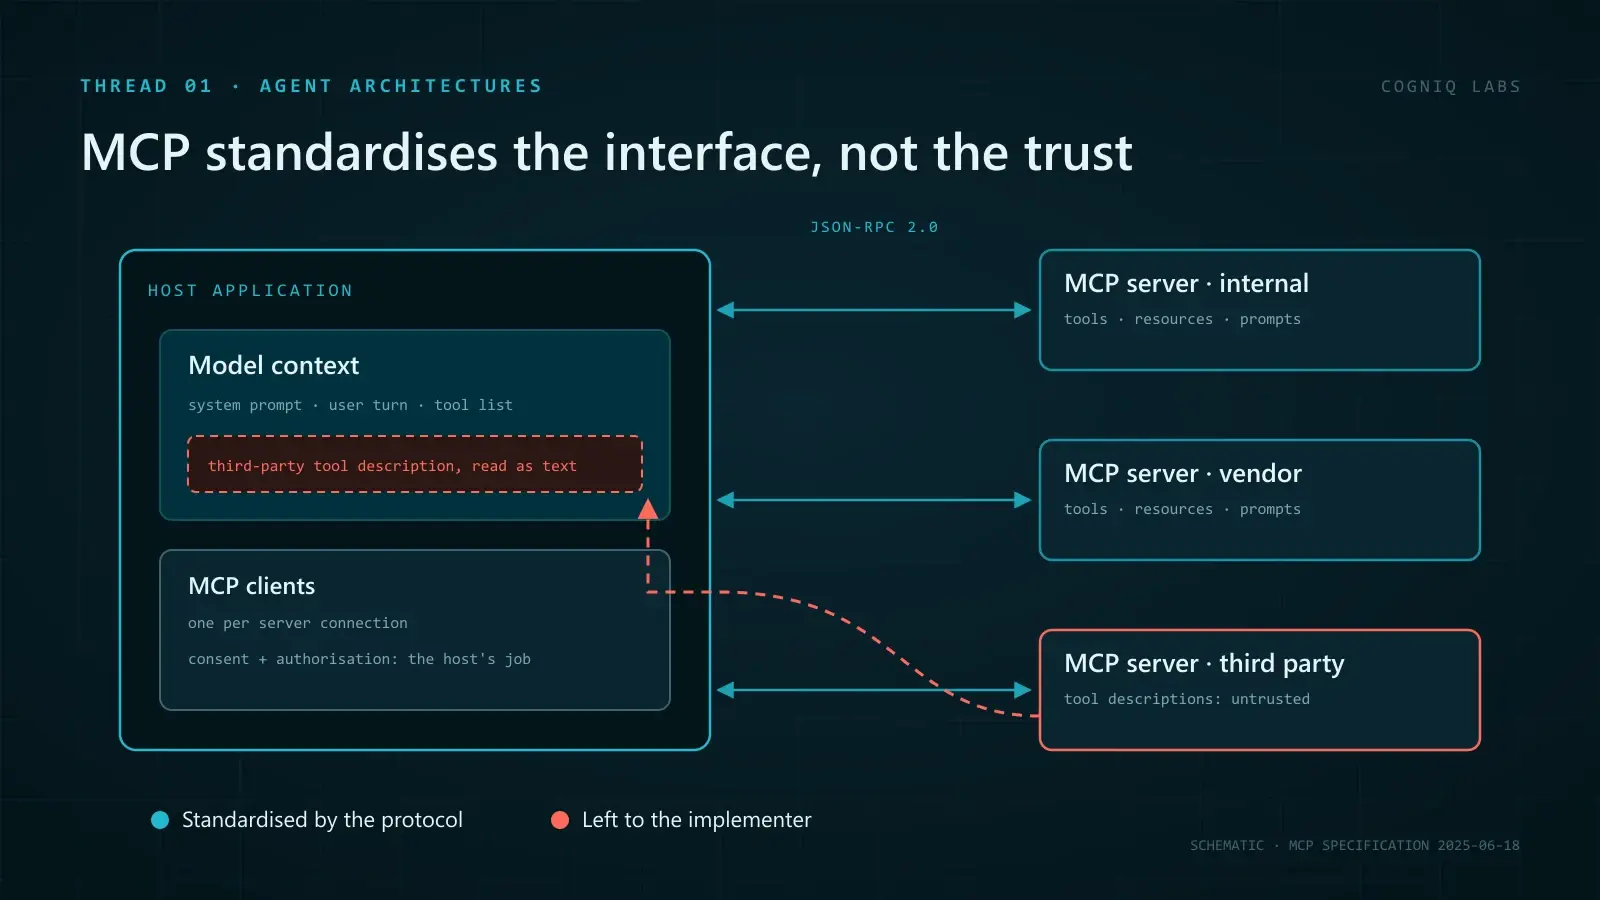 4 min read
MCP Standardises the Interface, Not the Trust
The Model Context Protocol gives agents one way to reach every tool. Its own specification says it cannot enforce security. What that leaves to you.
Agent ArchitecturesRead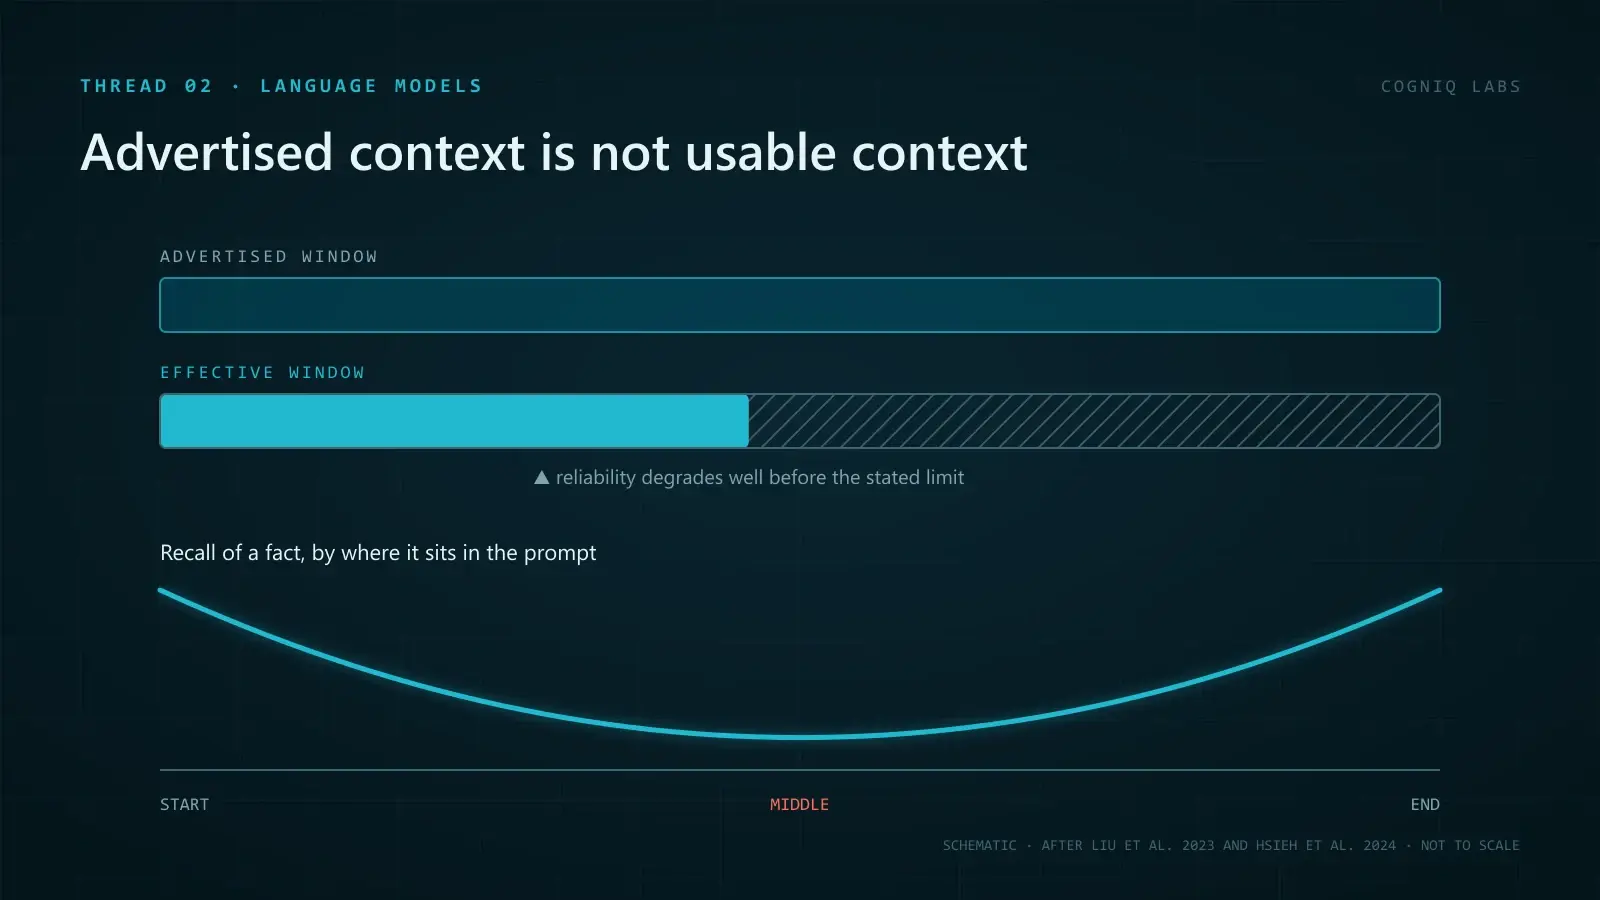 5 min read
Your Context Window Is Smaller Than Advertised
A context window is the most a model will accept, not the length it reliably uses. What long-context benchmarks found, and how to size prompts around it.
Language ModelsRead 5 min read
Why WebRTC Jitter Destroys Full-Duplex Voice AI
When packet jitter hits streaming audio, server VAD mistakes burst arrivals for human speech. Here is why full-duplex voice breaks on cellular links.
VoiceRead 4 min read
Why Multi-Agent Consensus Collapses into Hallucination
Without deterministic grounding, agent debate loops converge on shared falsehoods rather than truth. Here is the mechanism and how to anchor it.
AgentsRead 3 min read
Where the Tokens Actually Go in Long-Context Inference
A transparent look at KV-cache memory, bandwidth pressure, and why a large context window is not the same as reliable recall.
Language ModelsRead