Securing an AI Application Starts With What It Can Reach
You cannot make a language model refuse every attack. You can limit what it can read, change and send. A practical threat model for AI applications.
By Cogniq Labs ResearchEvidence policy
The usual question, "how do we stop the model being tricked?", has no reliable answer. Language models read instructions and data through the same channel, and a determined attacker can usually find wording that gets through.
The better question is: if the model is tricked, what can it do? That one has an answer, and the answer is entirely in your control. Securing an AI application mostly means limiting what the model can read, what it can change, and where it can send things, then treating everything it produces as untrusted.
Why AI applications break the usual model
In ordinary software, code and data are kept apart. A database stores strings; it does not obey them. Most security engineering rests on keeping that separation.
Language-model applications erase it. The indirect prompt injection paper put it directly: LLM-integrated applications blur the line between data and instructions. An attacker no longer needs access to your interface. They can place instructions in a web page, an email, a document or a support ticket, and wait for your application to retrieve it. The model reads the planted text with the same attention it gives your system prompt.
This is why prompt injection is not a filtering problem. Filters lower the success rate of known attack patterns, and that has value. But a defence that has to recognise every malicious sentence in advance will eventually miss one, so it cannot be the defence that everything else depends on.
Start with an inventory
Before any control, write down three lists. Most of the real security decisions come out of them.
| Question | List | What to look for |
|---|---|---|
| What can it read? | Every data source, index, file store and API it can query | Data the current user should not see; data from outside your organisation |
| What can it do? | Every tool, with its permissions | Writes, deletes, payments, messages, code execution, deployments |
| Who can talk to it? | Every route by which text reaches the model | Retrieved web pages, emails, uploaded files, tool results, other agents |
The third list is the one teams underestimate. The person typing into the chat box is only one of the model's inputs. Every document it retrieves and every result a tool returns is also input, and any of them may have been written by someone hostile.
The lethal trifecta
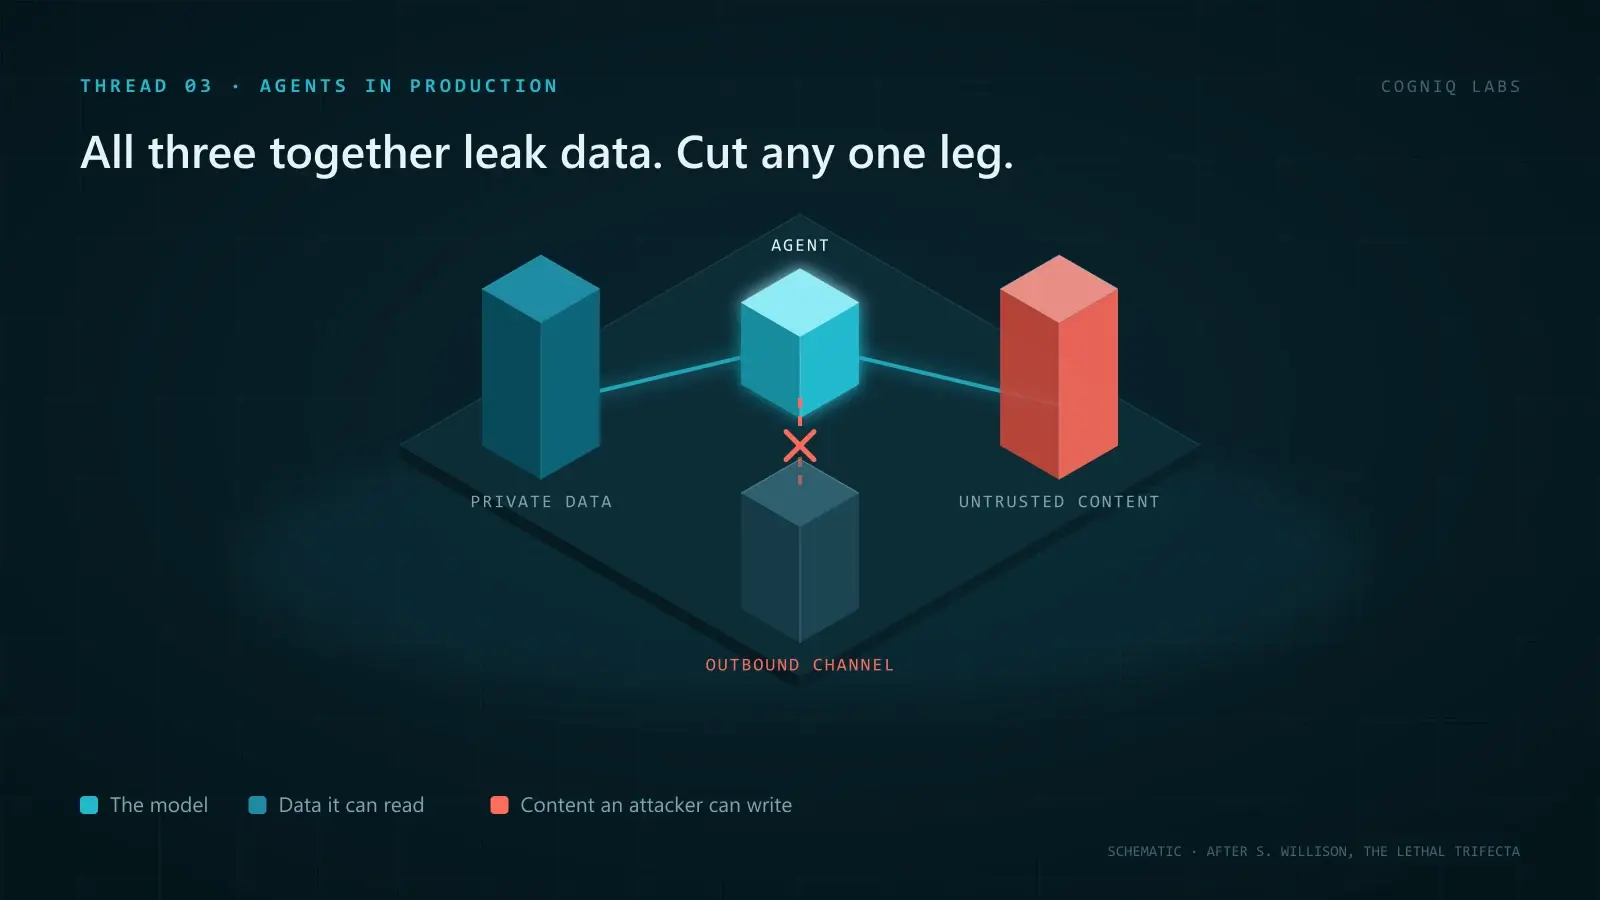
Simon Willison named the most dangerous combination the lethal trifecta: an agent that has
- access to private data,
- exposure to untrusted content, and
- the ability to communicate externally.
With all three, the attack is simple. Hostile text in some content the agent reads tells it to collect private data and send it somewhere: in an email, in a web request, even encoded in an image link the interface will fetch. No exploit of the model is needed, only instructions it follows.
The useful property of the trifecta is that removing any one leg breaks this attack. An agent that reads untrusted email and can send email should not also hold your customer database. An agent that holds your customer database and reads untrusted documents should not be able to make arbitrary web requests. Draw the three lists from the inventory, and check whether any single agent spans all three.
Controls that hold even when the model is fooled
These work without depending on the model resisting manipulation, which is why they come first.
Least privilege, per user. The model should act with the permissions of the person it is serving, not with a service account that can see everything. If a user cannot read a document directly, the application should not retrieve it for them. Retrieval systems frequently get this wrong, because the index was built with broad access and nobody added permission checks at query time.
Narrow tools. A tool that runs any SQL query is a different risk from a tool that looks up one order by its ID. Prefer specific tools with fixed parameters over general ones. OWASP calls the failure here "excessive agency": giving a model functionality, permissions or autonomy beyond what its task requires.
Human confirmation for irreversible actions. Sending, paying, deleting, publishing and deploying should require a person to approve the specific action, shown in plain terms, not a blanket permission granted once.
Treat output as untrusted input. Whatever the model produces goes through the same handling you would give text from an anonymous user. Escape it before rendering it as HTML. Never pass it to a shell or an eval. Use parameterised queries if it becomes part of one. OWASP lists this as "improper output handling", and it is how a manipulated answer becomes a conventional vulnerability.
Restrict outbound traffic. If an agent does not need to reach arbitrary URLs, do not let it. An allowlist of destinations removes the third leg of the trifecta for most applications.
Limit consumption. Set limits on tokens, tool calls, run time and spend per request and per user. Without them, a single malicious or looping request can run up a large bill. OWASP calls this "unbounded consumption".
The OWASP list, translated into decisions
The OWASP Top 10 for LLM Applications 2025 is the most practical reference for builders. Each entry maps to a design decision:
| OWASP 2025 | The decision it asks you to make |
|---|---|
| LLM01 Prompt Injection | Which inputs are untrusted, and what can a manipulated model do? |
| LLM02 Sensitive Information Disclosure | What can the model see that the current user should not? |
| LLM03 Supply Chain | Where do the model, its weights, plugins and dependencies come from? |
| LLM04 Data and Model Poisoning | Who can influence training, fine-tuning or retrieval data? |
| LLM05 Improper Output Handling | Where does model output flow, and is it escaped or validated there? |
| LLM06 Excessive Agency | Does each tool have the narrowest permissions that still work? |
| LLM07 System Prompt Leakage | Is anything secret in the system prompt? It should not be |
| LLM08 Vector and Embedding Weaknesses | Are permissions enforced at retrieval time, per user? |
| LLM09 Misinformation | Where do wrong answers cause harm, and who checks them? |
| LLM10 Unbounded Consumption | What stops one request from running forever or costing a fortune? |
Two entries are worth underlining. LLM07 is a reminder that a system prompt is not a secret store: assume users can extract it, so put no credentials or private rules in it. LLM08 is the retrieval problem above. A vector index that ignores permissions will happily return another customer's document to anyone who asks the right question.
The supply chain is ordinary software, plus weights
Models arrive as files downloaded from somewhere, run inside libraries with their own dependencies, and often call plugins or tool servers written by third parties. Each is a supply chain decision. Pin versions, prefer weight formats that store only tensors rather than serialised code, and review tool servers the way you would review any third-party code that runs with your credentials. A standard tool protocol makes integration easier; it does not vouch for whoever wrote the tool, which is the point of MCP standardising the interface but not the trust.
Log what it did, not just what it said
When something goes wrong, the question is what the model did: which documents it retrieved, which tools it called with which arguments, and what came back. Log all of it, per request, in a form a person can read. Many AI incidents are not crashes. They are correct-looking runs that did the wrong thing, which is why most agent failures never throw an error. Without the record there is no investigation, only a guess.
A threat model that fits on one page
For each feature, fill in one row. If a row cannot be filled in, that is the finding.
| Feature | Untrusted inputs | Data it can read | Actions it can take | Worst outcome | Control that holds if the model is fooled |
|---|---|---|---|---|---|
| Support assistant | Customer messages, ticket history | That customer's orders | Look up order, draft reply | Leaks another customer's order | Lookups scoped to the signed-in customer |
| Email triage agent | Every incoming email | Mailbox | Label, draft, forward | Forwards private mail to an attacker | Forwarding only to internal domains, with approval |
| Code assistant | Repository content, issues | Repository | Edit files, run tests | Runs a malicious command | Sandbox with no network or secrets |
The last column is the important one. Every entry in it should still work if the model has been completely taken over by hostile instructions.
Where the frameworks fit
The NIST Generative AI Profile, NIST AI 600-1, maps generative AI risks onto the NIST AI Risk Management Framework, and suits organisations that already govern risk that way. OWASP is closer to the code. Both are useful, and both are easy to satisfy on paper while missing the actual risk, which is why AI security frameworks often fail in practice. Use them as checklists to test a threat model against, not as a replacement for one.
What we do not know
We do not know of a general defence that makes a language model reliably distinguish instructions from data, and we would be suspicious of any product that claims one. Research continues on model-level defences, and some reduce attack success substantially in testing. Until one holds up against adaptive attackers in public, the sound assumption is that the model can be manipulated, and that security comes from what it is allowed to reach.
Sources
- OWASP Top 10 for LLM Applications 2025 — OWASP
- Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile (NIST AI 600-1) — NIST
- Not what you've signed up for: Compromising Real-World LLM-Integrated Applications with Indirect Prompt Injection — arXiv
- The lethal trifecta for AI agents: private data, untrusted content, and external communication — Simon Willison
Frequently asked questions
How do you secure an AI application?
Treat the model as an untrusted component. List everything it can read, everything it can do and everyone who can send it text, then cut each list to the minimum. Treat its output as untrusted input, require human approval for irreversible actions, and log every tool call.
What are the biggest security risks in LLM applications?
The OWASP Top 10 for LLM Applications 2025 puts prompt injection first, followed by sensitive information disclosure and supply chain risks. For applications that use tools, excessive agency, giving the model more permissions than it needs, is often what turns a manipulated answer into real damage.
Can prompt injection be prevented?
Not reliably by filtering alone, because a model reads instructions and data in the same channel. Filters reduce the rate of successful attacks. What prevents damage is limiting what a manipulated model can do: fewer permissions, no unnecessary outbound channels and confirmation before consequential actions.
What is the lethal trifecta in AI security?
A term coined by Simon Willison for agents that combine access to private data, exposure to untrusted content and the ability to communicate externally. With all three, an attacker who controls some content the agent reads can instruct it to send private data out. Removing any one of the three breaks that attack.
Which AI security framework should I follow?
The OWASP Top 10 for LLM Applications is the most practical starting point for builders, and NIST AI 600-1 suits organisations that already use the NIST AI Risk Management Framework. Neither replaces a threat model of your own application, which is where the useful decisions get made.
Related reading
MCP Standardises the Interface, Not the Trust
The Model Context Protocol gives agents one way to reach every tool. Its own specification says it cannot enforce security. What that leaves to you.
Prompt Injection Is Not a Filtering Problem
Published defences report low attack success rates on static benchmarks and fall over against adaptive attackers. What survives that is architecture.
What Agentic AI Actually Means, and What It Doesn't
Agentic AI is a model that chooses its own next step, not a chatbot with a new label. A working definition, where agents pay off and where they fail.