What Agentic AI Actually Means, and What It Doesn't
Agentic AI is a model that chooses its own next step, not a chatbot with a new label. A working definition, where agents pay off and where they fail.
By Cogniq Labs ResearchEvidence policy
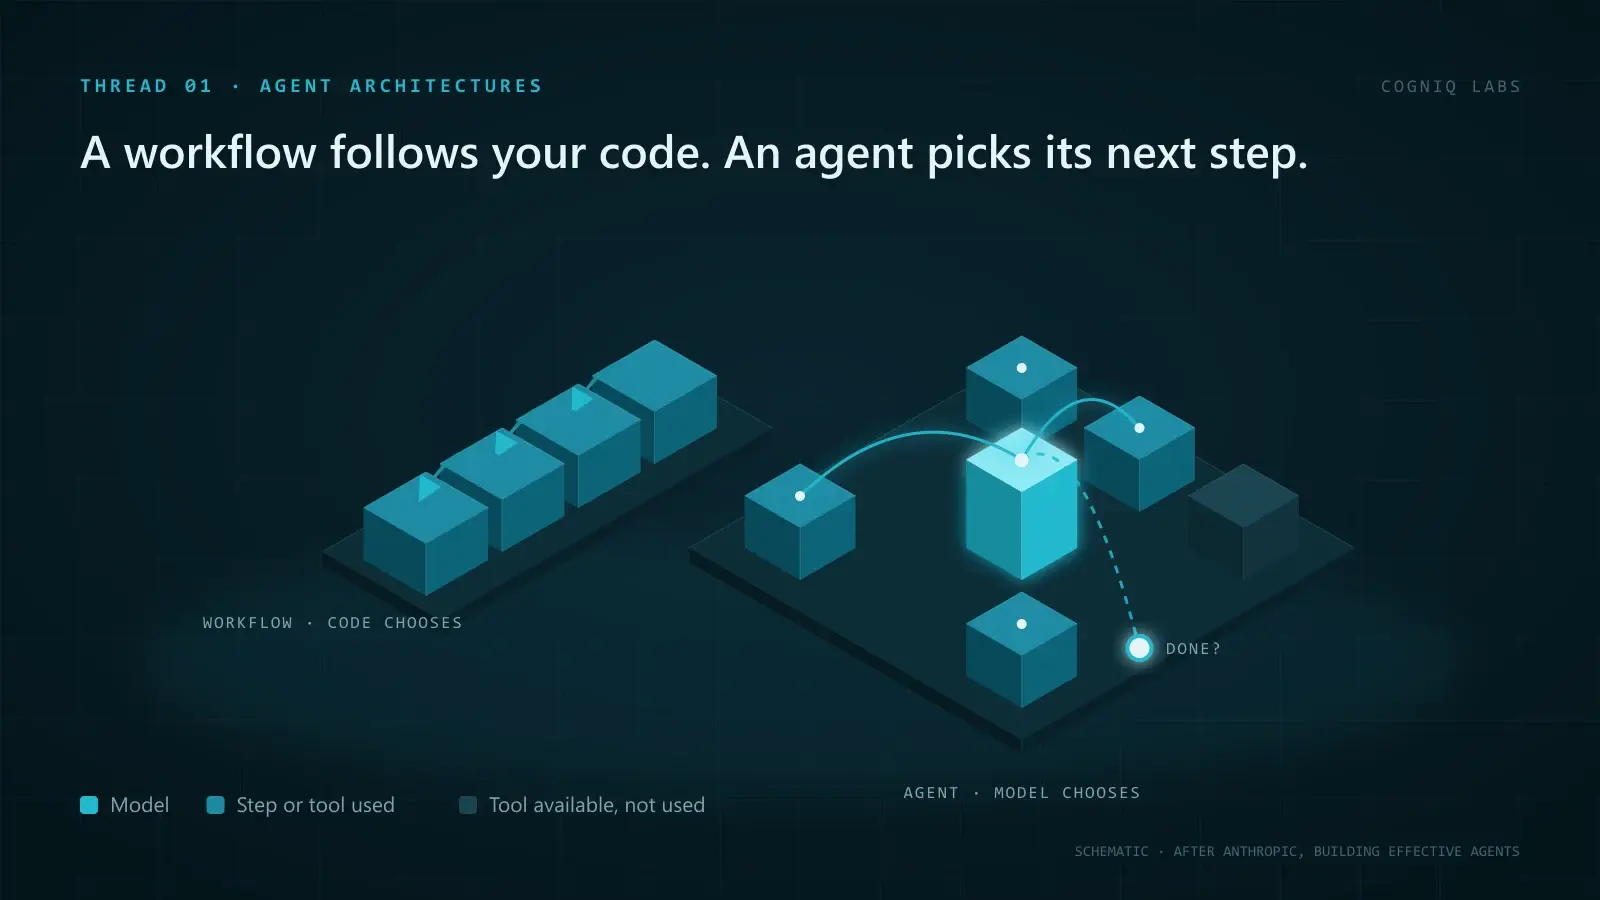
Agentic AI means a system in which a language model chooses its own next step. It reads the situation, picks a tool, looks at what came back, and decides whether to continue, change course or stop. That is the whole idea. Everything else, the frameworks, the dashboards, the word "autonomous" on a slide, is packaging around that loop.
The definition matters because the label is being stretched until it means nothing. If a product that runs a fixed script can call itself agentic, the word stops helping anyone decide what to build or buy.
A working definition
A useful definition has to separate systems that behave differently, not just sound different. The one that does this best comes from Anthropic's engineering guidance, which splits "agentic systems" into two kinds:
- Workflows: systems where models and tools are orchestrated through predefined code paths.
- Agents: systems where the model dynamically directs its own process and tool usage.
The line falls on one question: who decides the next step, your code or the model? If your code decides, you have a workflow, however many models it calls. If the model decides, you have an agent, however simple it looks.
Workflow or agent: why the distinction matters
The two behave differently in almost every way that affects a deployment.
| Workflow | Agent | |
|---|---|---|
| Who chooses the steps | Your code | The model |
| Number of steps | Known in advance | Decided at run time |
| Cost per task | Predictable | Varies, sometimes widely |
| Latency | Predictable | Varies with the path taken |
| Testing | Test each step | Test outcomes across many runs |
| Typical failure | A step breaks, visibly | The path goes wrong, often quietly |
| Best for | Repeatable processes | Open-ended problems |
The same guidance is blunt about which to prefer: find the simplest solution possible and add complexity only when it is needed. Agents earn their place on open-ended problems where it is difficult or impossible to predict the required number of steps. Most business processes are not like that. They are a sequence someone could write down, and a written-down sequence is cheaper, faster and easier to test than a model rediscovering it on every run.
The loop underneath every agent
Strip away the branding and nearly every language-model agent runs the same loop:
- Observe: read the task, the conversation so far and the results of earlier actions.
- Reason: decide what to do next.
- Act: call a tool, such as a search, a database query, a code runner or an API.
- Check: read the result and decide whether the task is done.
The pattern was made explicit in the ReAct paper, which had models alternate between writing reasoning steps and taking actions, so the reasoning could steer the actions and the actions could bring in information the model did not have. Most agent frameworks since are variations on that loop with more tools, more memory and more structure around it.
The fourth step is the one that decides whether an agent is useful. A model that cannot tell when it has finished, or cannot tell that it has failed, will either stop too early or keep going, spending money on a task it has already got wrong.
Degrees of agency
"Agentic" is not a yes-or-no property. Systems differ along four dimensions, and it is more informative to say where a system sits on each than to argue about the label.
| Dimension | Less agentic | More agentic |
|---|---|---|
| Who plans the steps | Fixed in code | Chosen by the model |
| How many actions per task | One tool call | Dozens, with branching |
| How long without a human | Every step approved | Hours unattended |
| What it can change | Read-only | Writes, sends, pays, deploys |
The last row deserves the most attention. An agent that can only read can waste time and money. An agent that can write to a database, send email or move money can do damage, and every step up that row needs a matching step up in controls. That is a security question as much as a design one, and it is why a standard interface for tools does not settle whether a tool should be trusted.
Why the label got stretched
Gartner's June 2025 forecast predicts that over 40 percent of agentic AI projects will be canceled by the end of 2027, citing escalating costs, unclear business value and inadequate risk controls. The same release describes "agent washing", the rebranding of existing chatbots, assistants and robotic process automation as agents, and estimates that only around 130 of the thousands of vendors claiming agentic capabilities are genuine.
Whatever one makes of the exact numbers, the pattern is familiar. When a word becomes a buying criterion, everything acquires it. The practical defence is the question from the definition: in this product, who decides the next step? If the answer is a fixed script with a model filling in text, it may be a perfectly good product. It is not an agent, and it should be evaluated, priced and tested like the workflow it is.
Where agents earn their cost
Agents are worth their unpredictability when three things are true at once.
The path cannot be known in advance. Debugging an unfamiliar codebase, researching a question across sources that have to be discovered, or investigating an incident from logs are all tasks where the next step depends on what the last one found.
The result can be checked. Code either passes its tests or does not. A research answer either cites sources that say what it claims or does not. Agents do best where there is something firm to check against, because the check is what catches the wrong path.
The task is worth the cost. An agent may make many model calls where a workflow makes two. That is acceptable for a task that would otherwise take a person an afternoon, and absurd for one a lookup table could answer.
When all three hold, an agent can do work no fixed pipeline could. When any one is missing, a workflow is usually the better system.
Where agents fail
Errors compound
Each step an agent takes has some chance of going wrong, and the chances multiply. As illustrative arithmetic, assuming independent steps: an agent that gets each step right 95 percent of the time completes a 20-step task without error only about 36 percent of the time, because 0.95 multiplied by itself 20 times is roughly 0.36. At 99 percent per step, the same task succeeds about 82 percent of the time.
Real steps are not independent, and good agents recover from some mistakes, so the true figures differ. The shape is the point: long tasks punish small error rates, which is why shortening the path is often worth more than improving the model.
Failures are quiet
A workflow that breaks usually throws an error. An agent that goes wrong usually keeps going, produces a confident result and reports success. That is why most agent failures never throw an error, and why monitoring built for ordinary software misses them.
Nobody can see why
When an agent chooses its own path, the path is the explanation, and if it is not recorded nobody can review it. A supervisor who cannot see what an agent did cannot correct it, which is the legibility problem in autonomous agents.
More agents is not more reliable
Adding agents to check each other sounds like redundancy, but agents built on similar models share blind spots, and their agreement can be agreement on the same mistake. We have written about how multi-agent consensus collapses into hallucination, and about the latency cost of stateful multi-agent loops.
How long can an agent work alone?
One of the more careful attempts to measure this is METR's study of how long a task AI agents can complete. It measures tasks by how long they take skilled humans, and finds frontier models of early 2025 had a 50 percent success "time horizon" of around 50 minutes on its software tasks, with that horizon doubling roughly every seven months since 2019.
Two cautions keep this figure honest. It is a 50 percent success rate, so at that length the agent fails half the time. And it is measured on software tasks with clear checks, which are the kinds of task agents do best. It is evidence that capability is rising quickly, not evidence that an agent can be left alone with an afternoon of your business's work.
A test before you build one
Before choosing an agent over a workflow, answer these in writing:
- Can you list the steps? If yes, build a workflow, and use the model only where judgement is needed.
- What does the agent need to touch? List every tool and every permission. Remove any it does not strictly need.
- How will you know it worked? Name the check. If there is no check, there is no way to tell a good run from a confident wrong one.
- What is the worst action it could take? Put a human approval in front of anything irreversible.
- What will a task cost? Measure the distribution over many runs, not one demo, since agent costs have long tails.
- What is recorded? Every step, tool call and result should be logged in a form a person can read.
If the answers are uncomfortable, that is useful information. It usually means the right first version is a workflow with one agentic step inside it, not an agent with a workflow's job.
What we do not know
We do not know how quickly the reliability of long agent runs will improve in practice, outside benchmarks with clean checks. Time-horizon measurements are rising fast, but most business tasks have fuzzier success criteria than software tests, and we have not seen good public evidence on how agents perform on those. Until there is, the safe assumption is that an agent is as reliable as the check at the end of its loop, and no more.
Sources
Frequently asked questions
What is agentic AI in simple terms?
It is a system in which a language model decides what to do next, calls tools to do it, looks at the result and repeats until it judges the task finished. The defining feature is that the model, not a fixed program, chooses the sequence of steps.
What is the difference between an AI agent and a workflow?
In a workflow, your code decides the steps and the model fills in parts of them. In an agent, the model decides the steps itself. Anthropic's guidance draws the line exactly there, and recommends workflows whenever the steps can be known in advance.
Is a chatbot with tools an AI agent?
Not necessarily. A chatbot that calls one tool when asked and returns the answer is closer to a workflow. It becomes an agent when it plans several steps, chooses between tools, reacts to what it finds and decides on its own when to stop.
Why do agentic AI projects fail?
Mostly because small error rates compound over many steps, because failures are often silent rather than raised as errors, and because cost and value were never measured. Gartner predicts over 40 percent of agentic AI projects will be canceled by the end of 2027 for reasons of cost, unclear value or weak risk controls.
When should I use an AI agent instead of a fixed pipeline?
When the number and order of steps genuinely cannot be predicted, the task is worth the extra cost and latency, and you can check the result. If you can write the steps down, write them down as code and let the model handle only the parts that need judgement.
Related reading
MCP Standardises the Interface, Not the Trust
The Model Context Protocol gives agents one way to reach every tool. Its own specification says it cannot enforce security. What that leaves to you.
Prompt Injection Is Not a Filtering Problem
Published defences report low attack success rates on static benchmarks and fall over against adaptive attackers. What survives that is architecture.
The Legibility Problem in Autonomous Agents
An autonomous agent is governable only when operators can reconstruct its goals, evidence, decisions, actions, and uncertainty.