THREAD 03
Agents in Production
What separates a compelling agent demo from a secure, observable, resilient production system.
Open question
How do we make failures visible early enough for operators to intervene?
How we investigate
Incident patterns, threat modelling, evaluation design, and observability schemas.
 4 min read
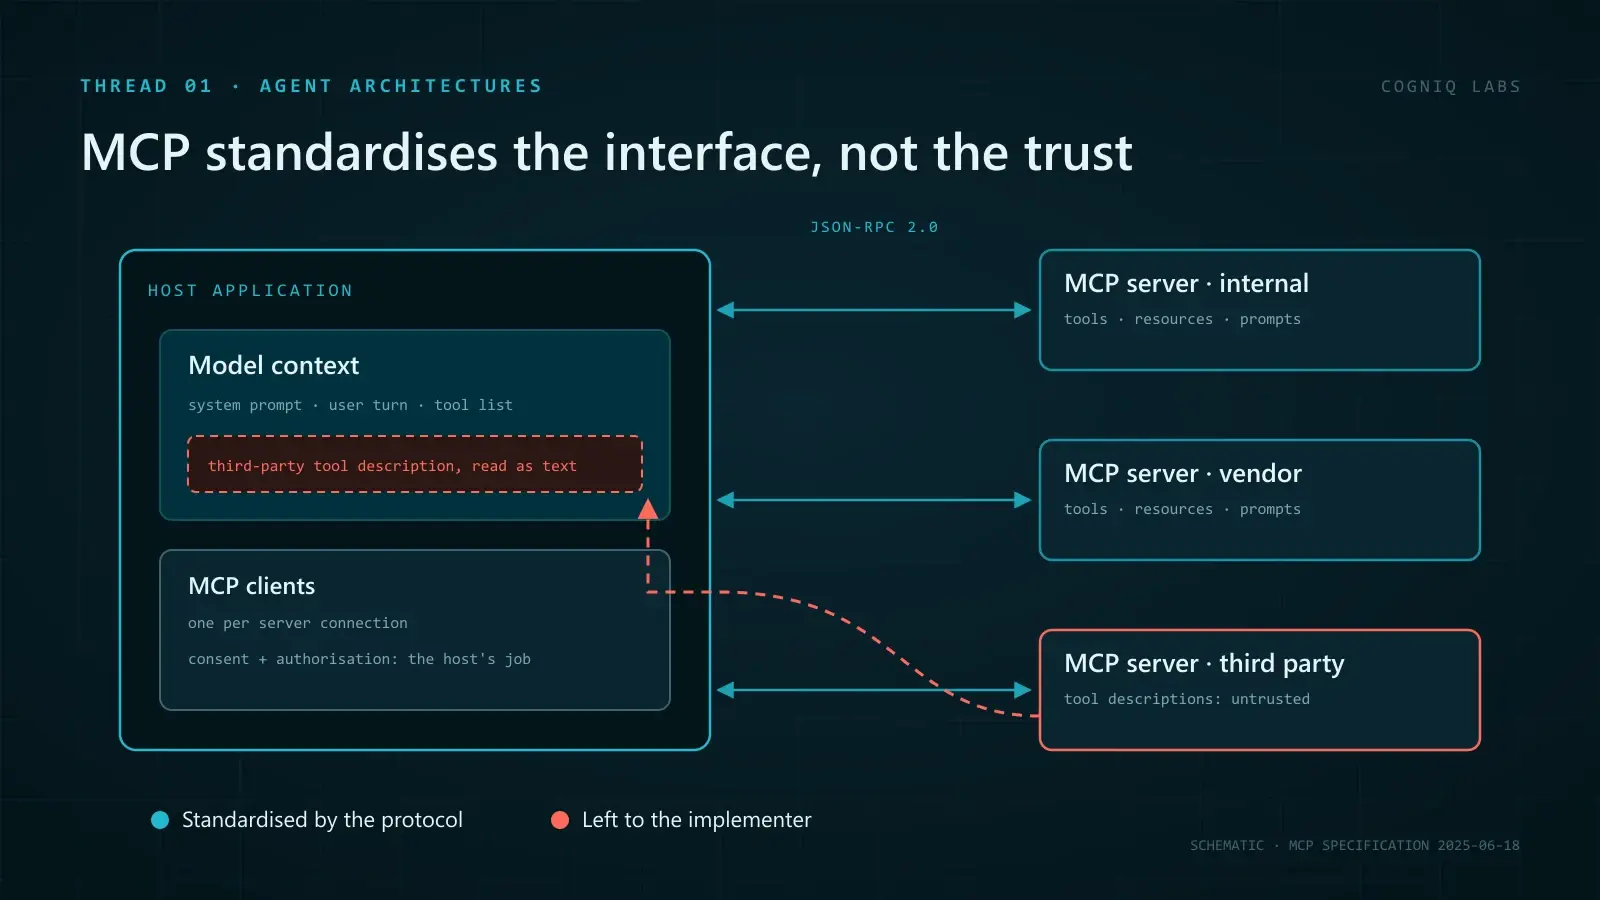
MCP Standardises the Interface, Not the Trust
The Model Context Protocol gives agents one way to reach every tool. Its own specification says it cannot enforce security. What that leaves to you.
Agent ArchitecturesRead 4 min read
Why Multi-Agent Consensus Collapses into Hallucination
Without deterministic grounding, agent debate loops converge on shared falsehoods rather than truth. Here is the mechanism and how to anchor it.
AgentsRead 3 min read
Where the Tokens Actually Go in Long-Context Inference
A transparent look at KV-cache memory, bandwidth pressure, and why a large context window is not the same as reliable recall.
Language ModelsRead 3 min read
The Hidden Latency Cost of Stateful Multi-Agent Loops
How context growth and sequential model calls make multi-agent systems slower—and how to decide when extra roles are worth it.
Agent ArchitecturesRead 2 min read
Why RAG Fails When the Chunk Score Is High
Similarity can retrieve a topically related chunk that does not support the answer. Here is how to test retrieval for evidence, not proximity.
RetrievalRead 5 min read
Prompt Injection Is Not a Filtering Problem
Published defences report low attack success rates on static benchmarks and fall over against adaptive attackers. What survives that is architecture.
AI securityRead 4 min read
We Blamed AI Overviews. It Was Our Titles.
Nine hundred impressions at positions three to ten, and zero clicks. We assumed zero-click search. The Search Console data said something duller.
AI search optimizationRead 5 min read
Why AI Security Frameworks Fail in Practice
Frameworks describe controls for a system with a boundary. LLM applications dissolve that boundary, and the checklist stays green while the gap opens.
AI securityRead 5 min read
Which Model Should You Actually Run in Production
Leaderboards rank models on a distribution your workload does not resemble. The four axes that decide it, and how to build the comparison that matters.
Language ModelsRead 5 min read
Why Voice Agents Feel Broken at 800ms
Total latency is the wrong number to optimise. What decides whether a voice agent feels alive is time to first audio, and where those milliseconds go.
Voice SystemsRead 5 min read
Most Agent Failures Never Throw an Error
An agent that crashes is the cheap case. The expensive failures return a confident, well-formed, wrong answer, and nothing in the stack notices.
Autonomous AI AgentsRead 3 min read
The Legibility Problem in Autonomous Agents
An autonomous agent is governable only when operators can reconstruct its goals, evidence, decisions, actions, and uncertainty.
Agent ArchitecturesRead